//
Research
Independent benchmarks that test the limits of frontier models
At Deccan AI research, our mission is to deeply understand, evaluate, and advance the science of foundation models, enabling clearer insights for the AI community.
Great! We'll ensure our research lands in your inbox without fail
Oops! Something went wrong while submitting the form.
// Collaborated and co-authored with ML engineers at
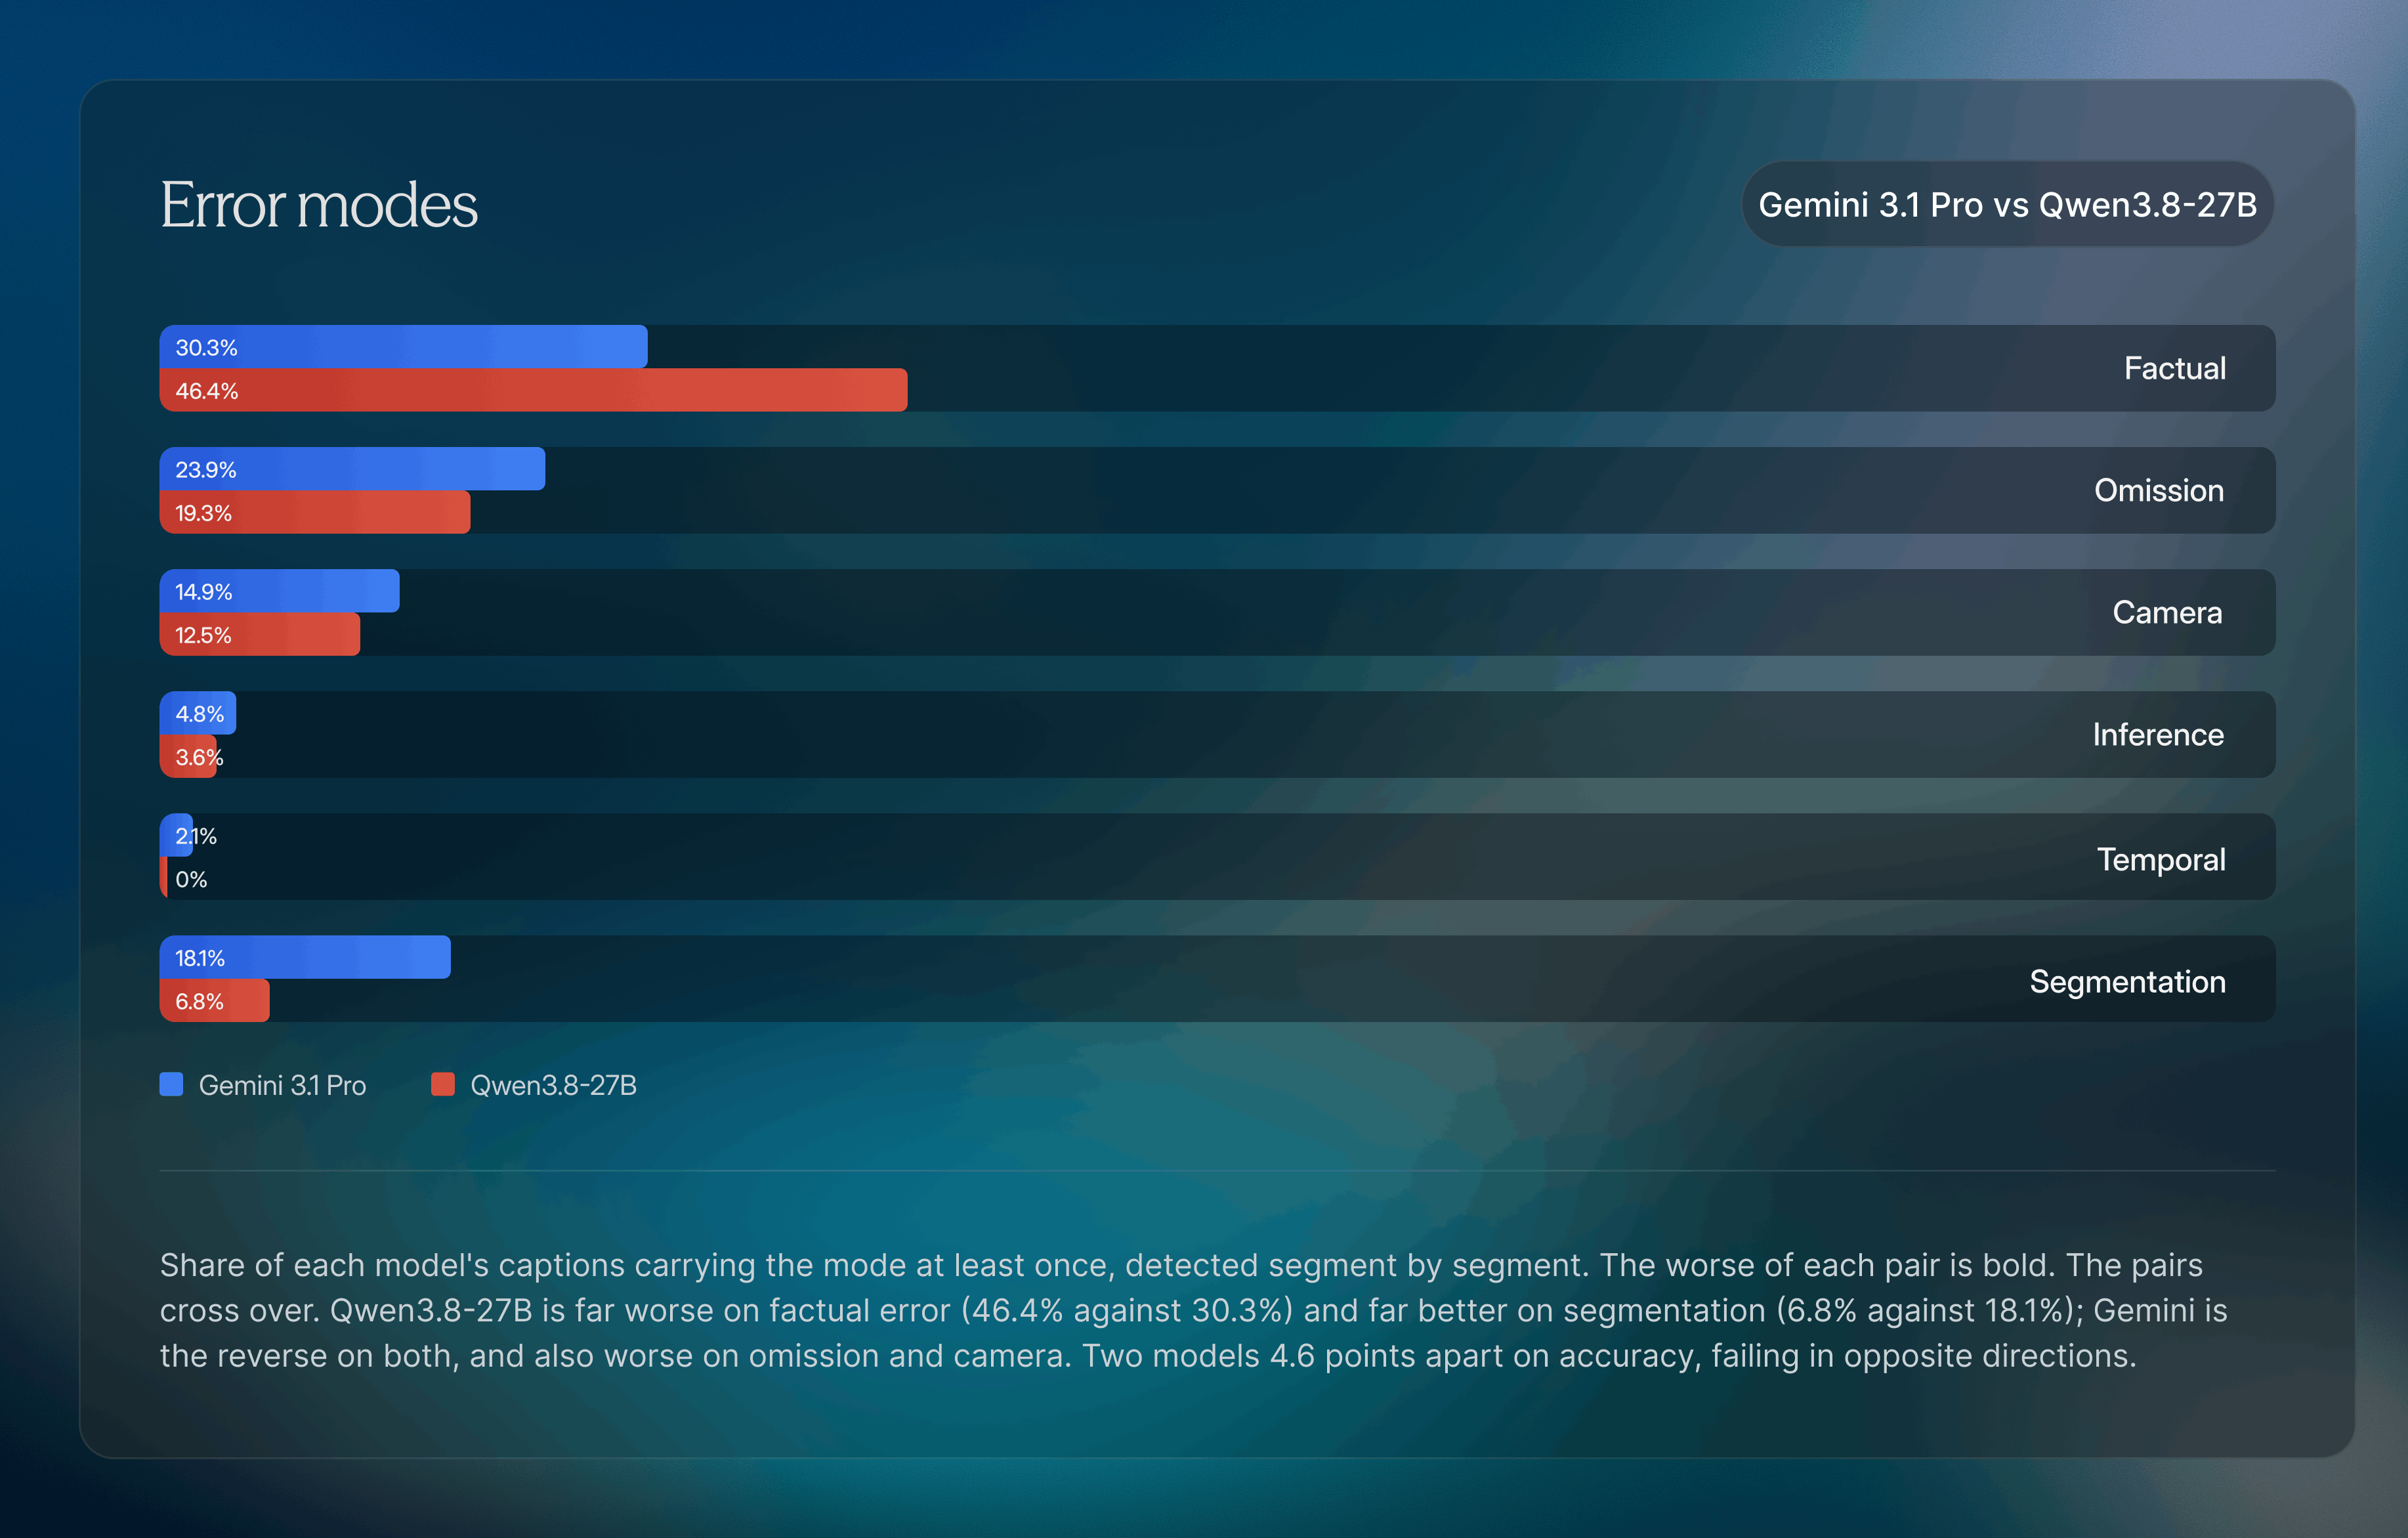
Introducing CaptionBench: A Stalemate on the Leaderboard Masks Distinct Failure Modes
In this video captioning benchmark, we evaluated six video captioning models by having trained reviewers rewrite and grade every caption against the footage, then checked what those corrections revealed against what the leaderboard scores showed.
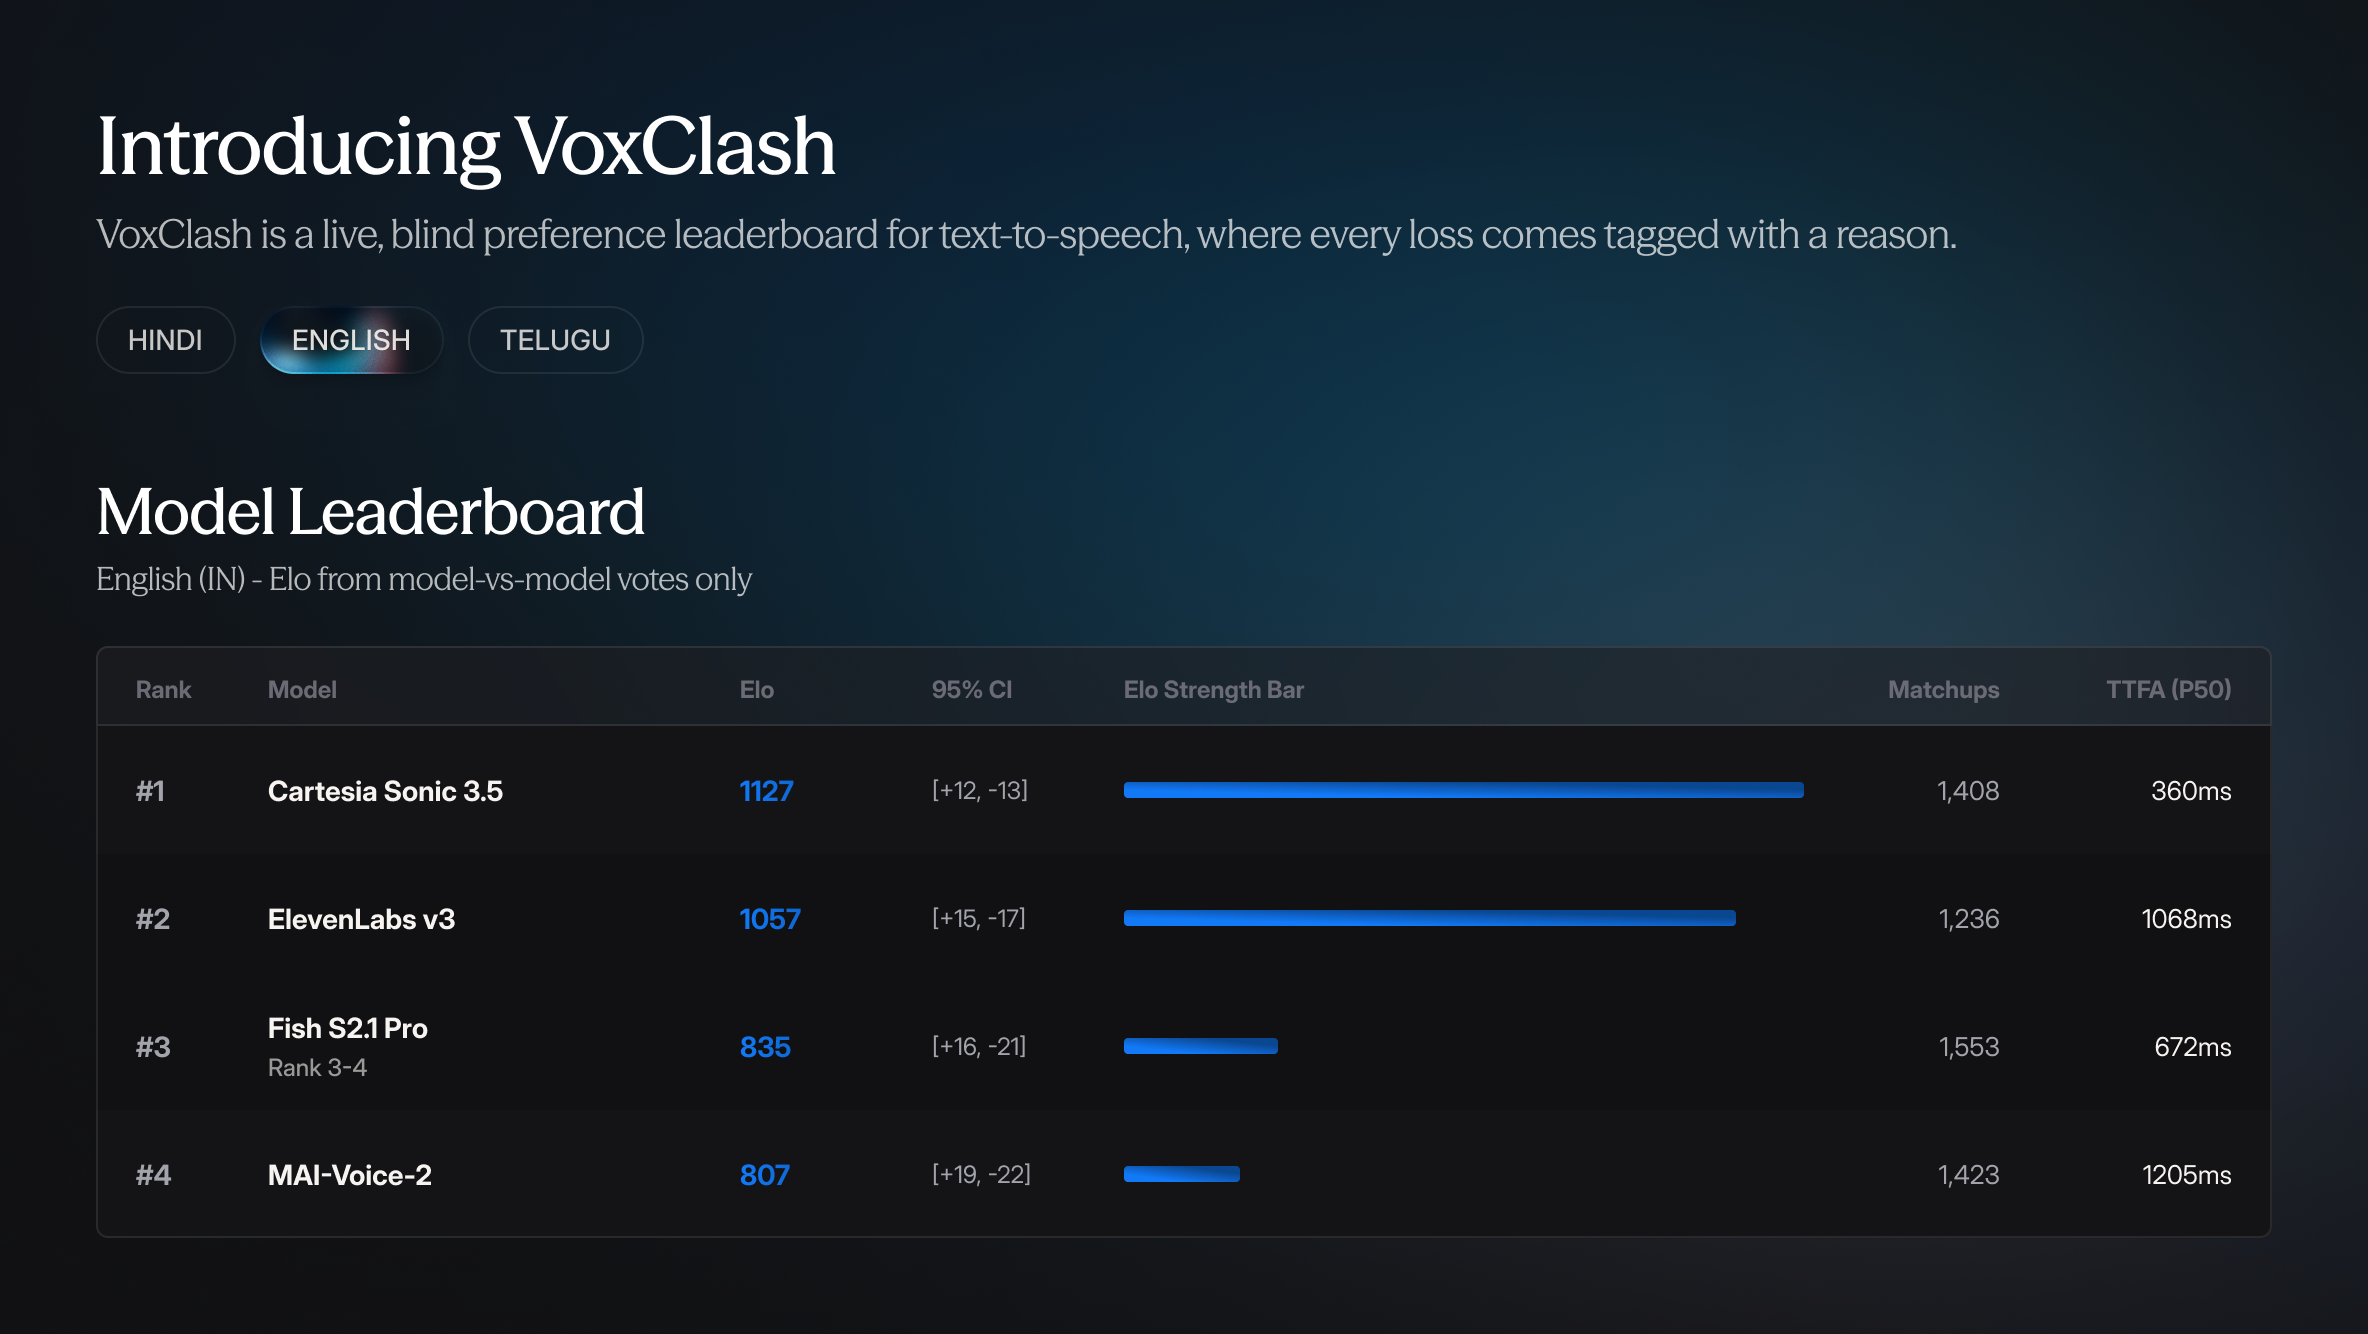
Introducing VoxClash: A TTS leaderboard that reveals where exactly a model breaks down.
TTS outputs finally sound human. Yet, picking the right model for your language and use case is still a guessing game. VoxClash is our shot at fixing that.