Today, we’re introducing VoxClash TTS 2.0, the next version of our blind-vote leaderboard for text-to-speech. It grew from three languages to nine and from nine models to sixteen, and it now ranks models by use case, so you can see which one listeners prefer for the job you’re hiring a voice to do.
We built it because of how teams choose a voice. Nobody asks which model is best in the abstract. They ask which one should read a billing reminder in Hindi, or take a support call in Tamil. One overall rank cannot answer that, and the gap between the two questions is big enough to change the pick.
Across the nine languages, Cartesia Sonic 3.6 has the highest Elo on six boards. ElevenLabs v4 leads English (India), and Gemini 3.1 Flash TTS leads Tamil and Urdu.
Narrow the use case and the overall leader tends to lose its lead
Each language has an overall ranking built from every script we test, plus rankings for five use cases: Appointment, Billing, News, Support and Misc, which is every script outside the other four. The overall and use-case rankings can disagree.
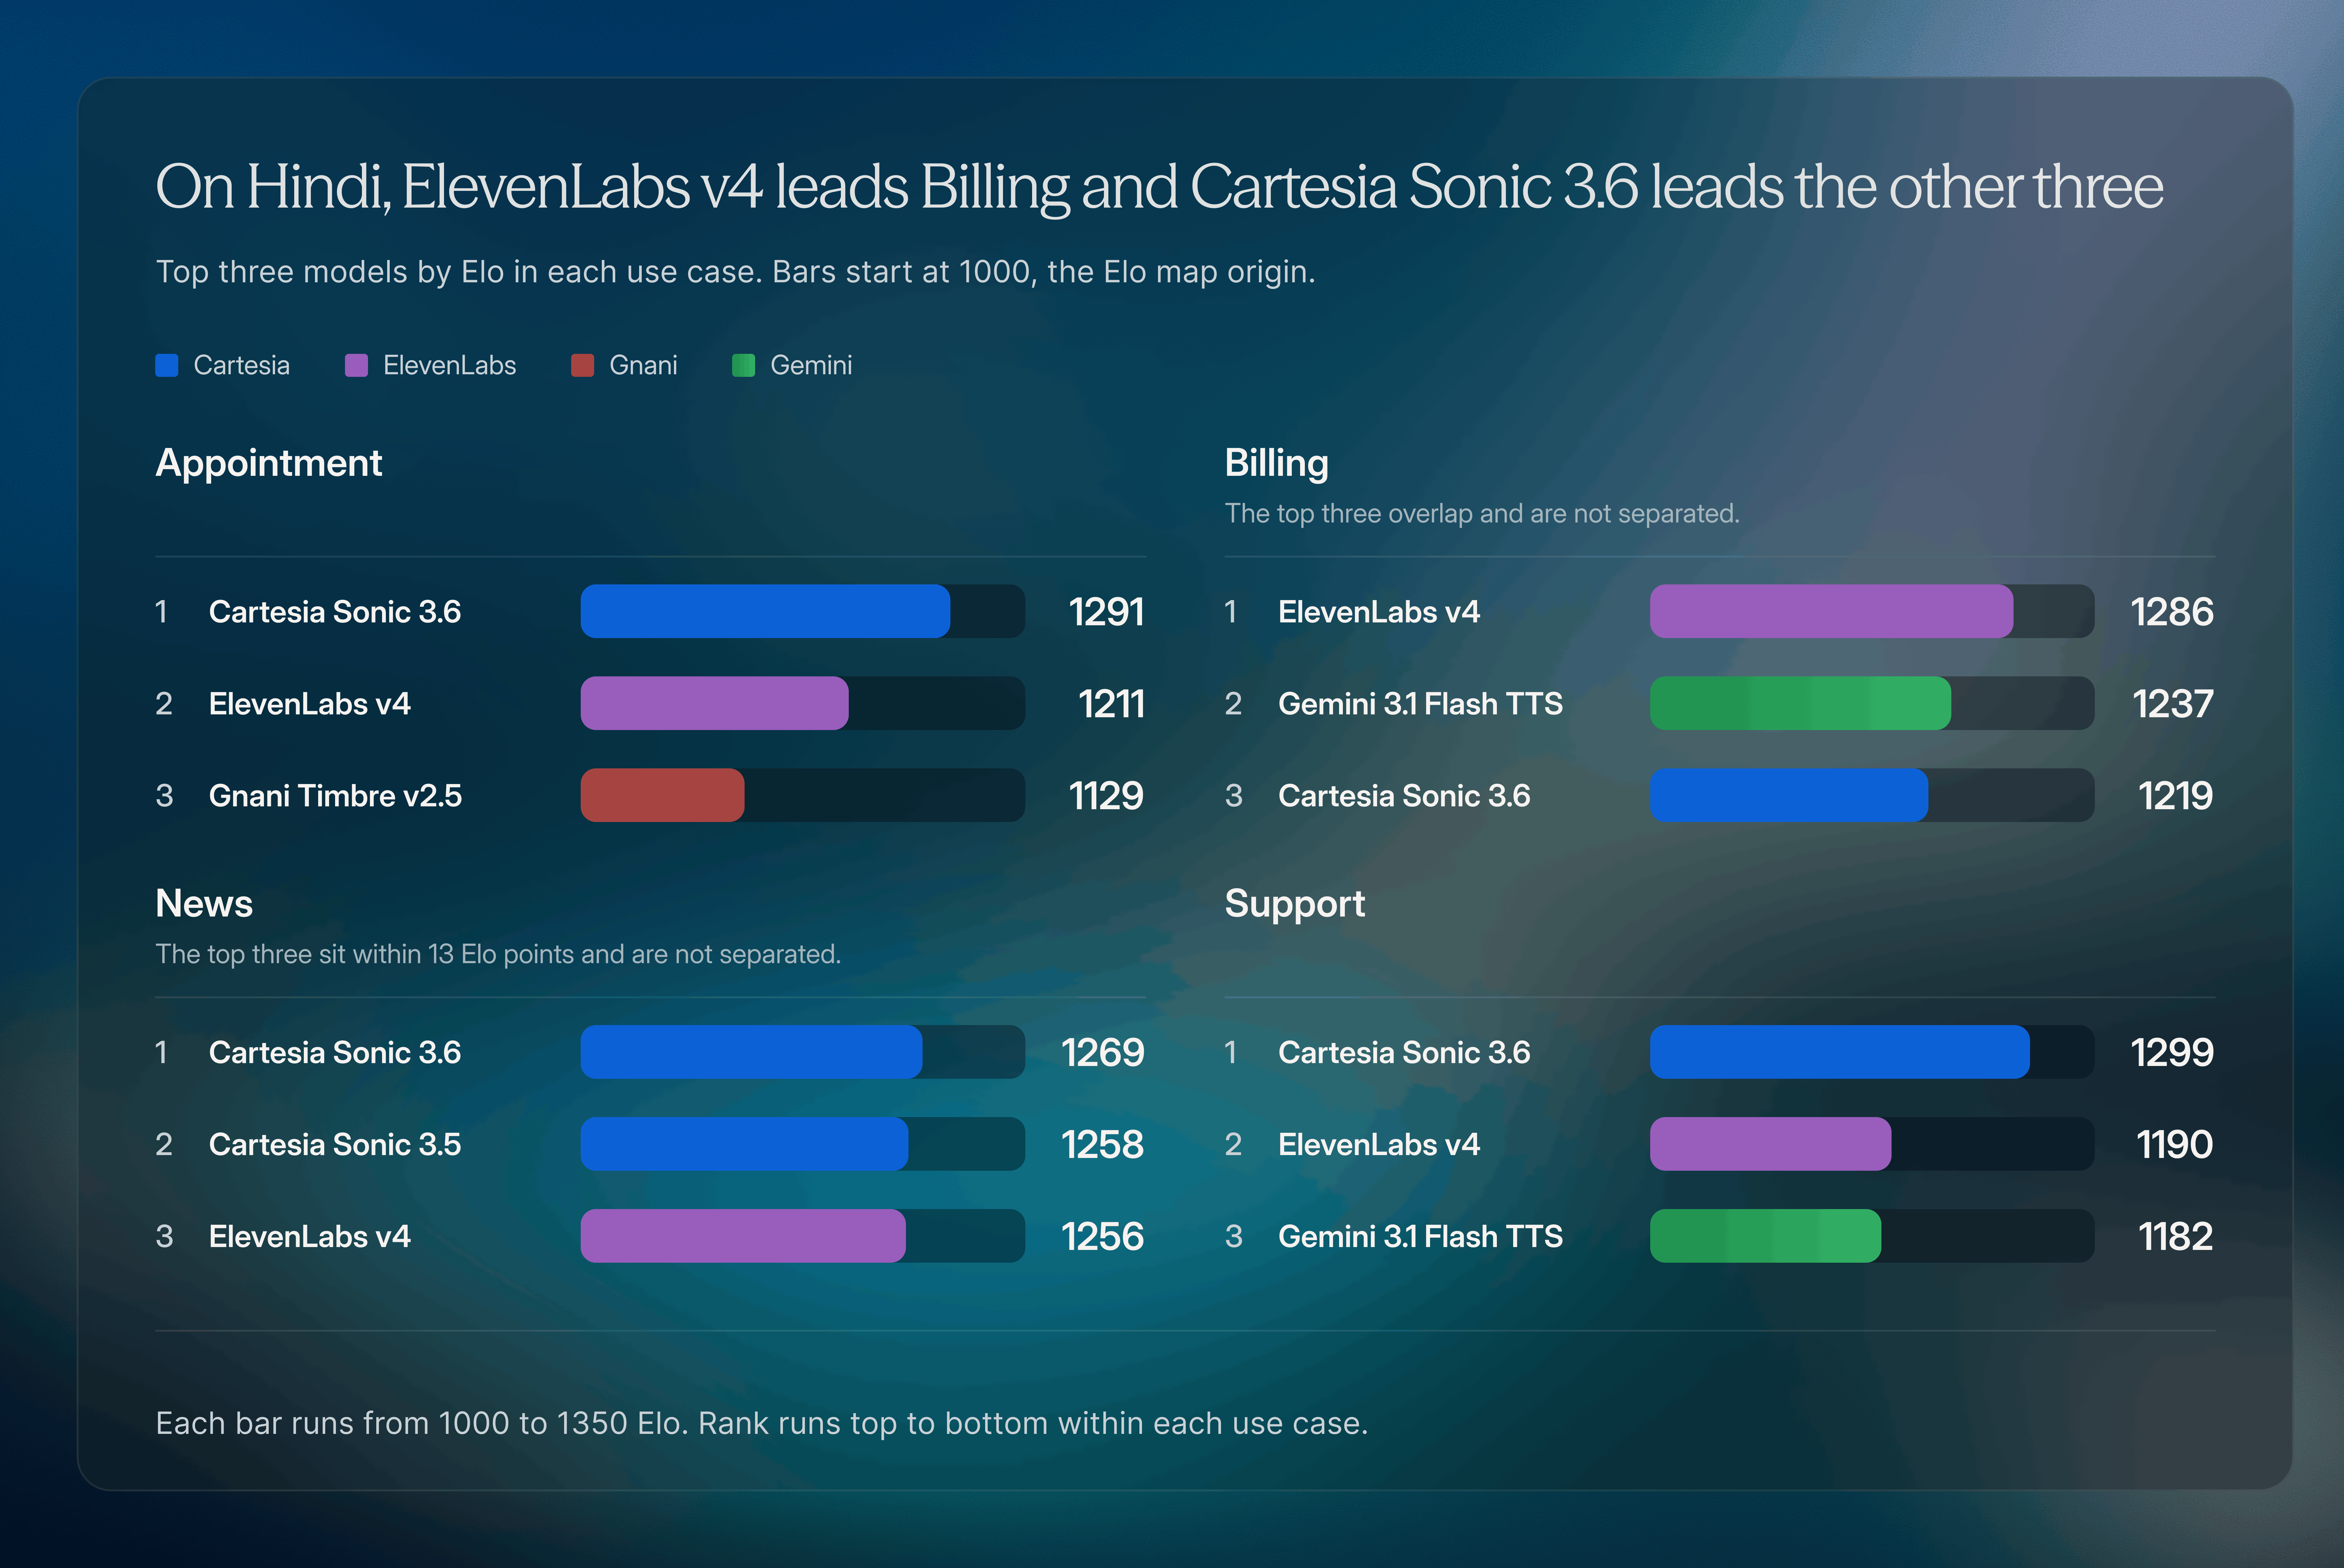
Take Hindi. Cartesia Sonic 3.6 ranks first overall but third on Billing. ElevenLabs v4, second overall, ranks first on Billing, and Gemini 3.1 Flash TTS, fourth overall, ranks second.
The winner also depends on the language. Billing went to ElevenLabs v4 in Hindi and to Cartesia Sonic 3.5 in English (India). Support went to Sonic 3.6 in Hindi and to ElevenLabs v3 in English (India).
Some boards need no second look. In Telugu, Sonic 3.6 leads all four named use cases, so the overall board is a safe guide there.
On Hindi Billing and News, three models have overlapping rank ranges, because each use case holds fewer votes than the whole board. Read those ranks as a shortlist until more votes narrow the intervals.
Six new languages, and no single leader
VoxClash TTS 2.0 adds Bengali, Urdu, Tamil, Gujarati, Malayalam and Marathi to English (India), Hindi and Telugu. Only approved raters who are native speakers cast counted votes, and native speakers review every script before it enters the arena.
Gemini 3.1 Flash TTS leads Tamil and Urdu for different reasons. Urdu is a five-model board with no Cartesia on it. On Tamil, Gemini’s lead over Sonic 3.6 sits inside the confidence interval, and the two share a rank range of 1 to 2.
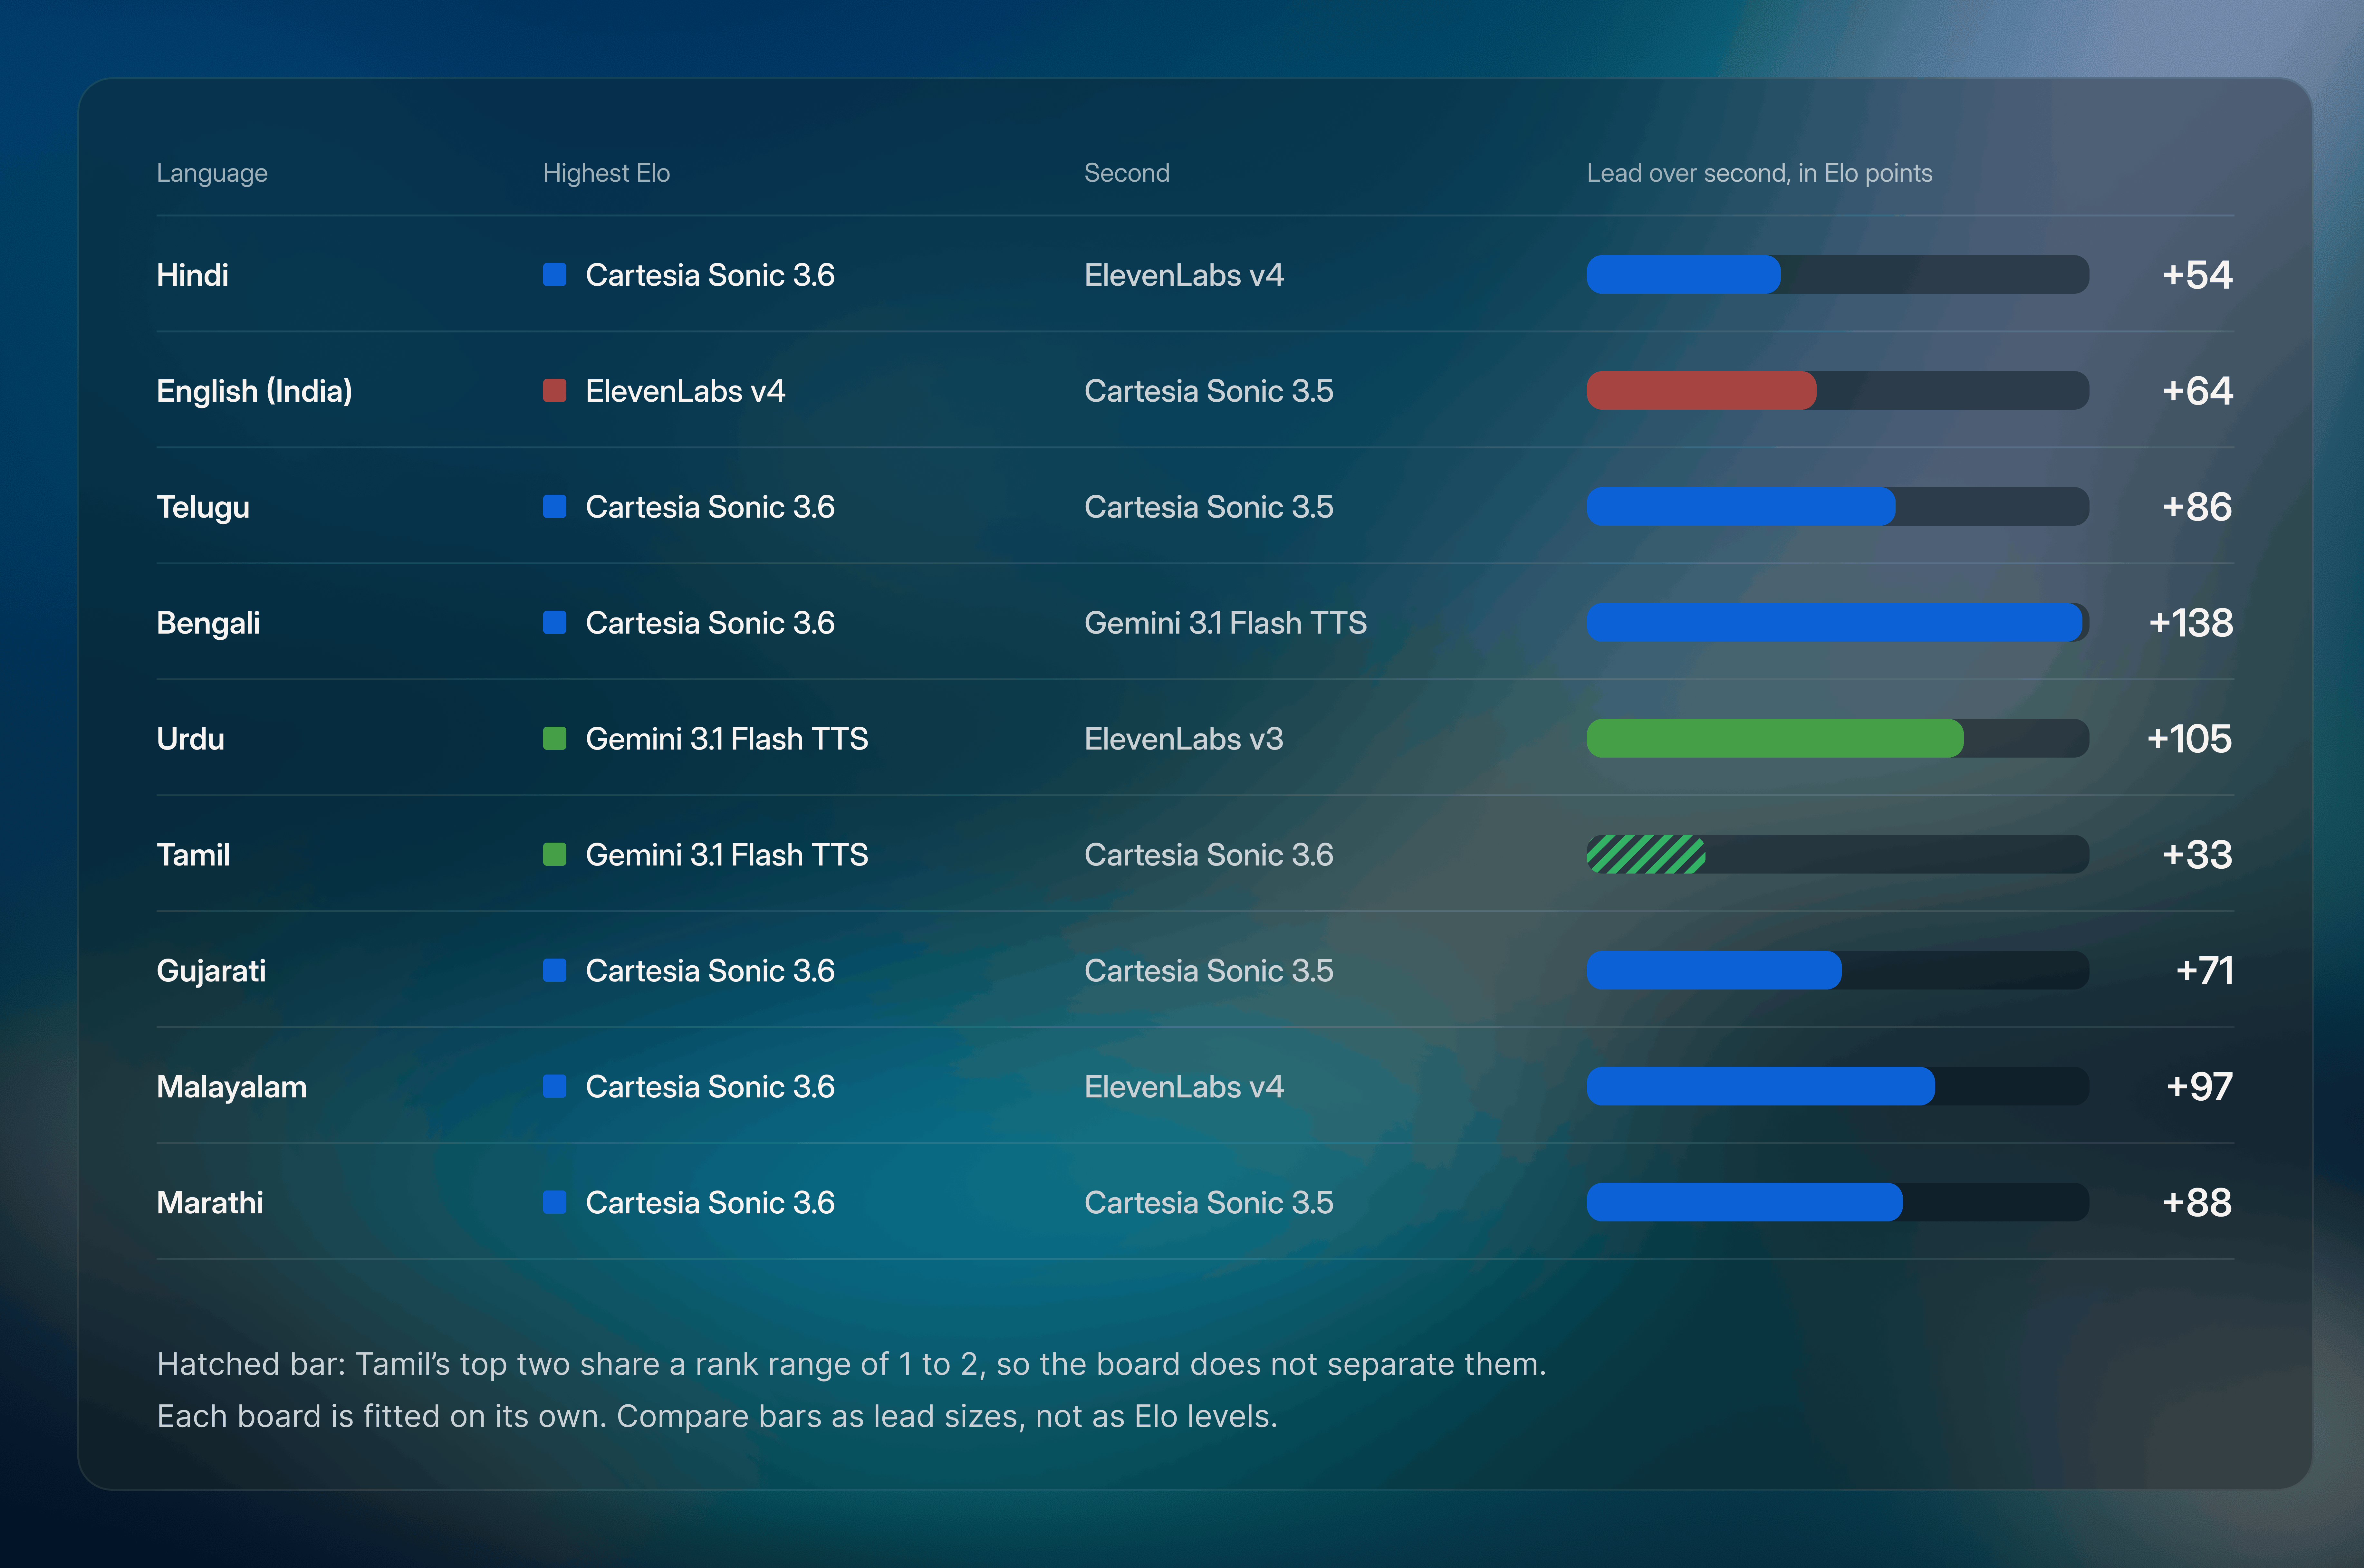
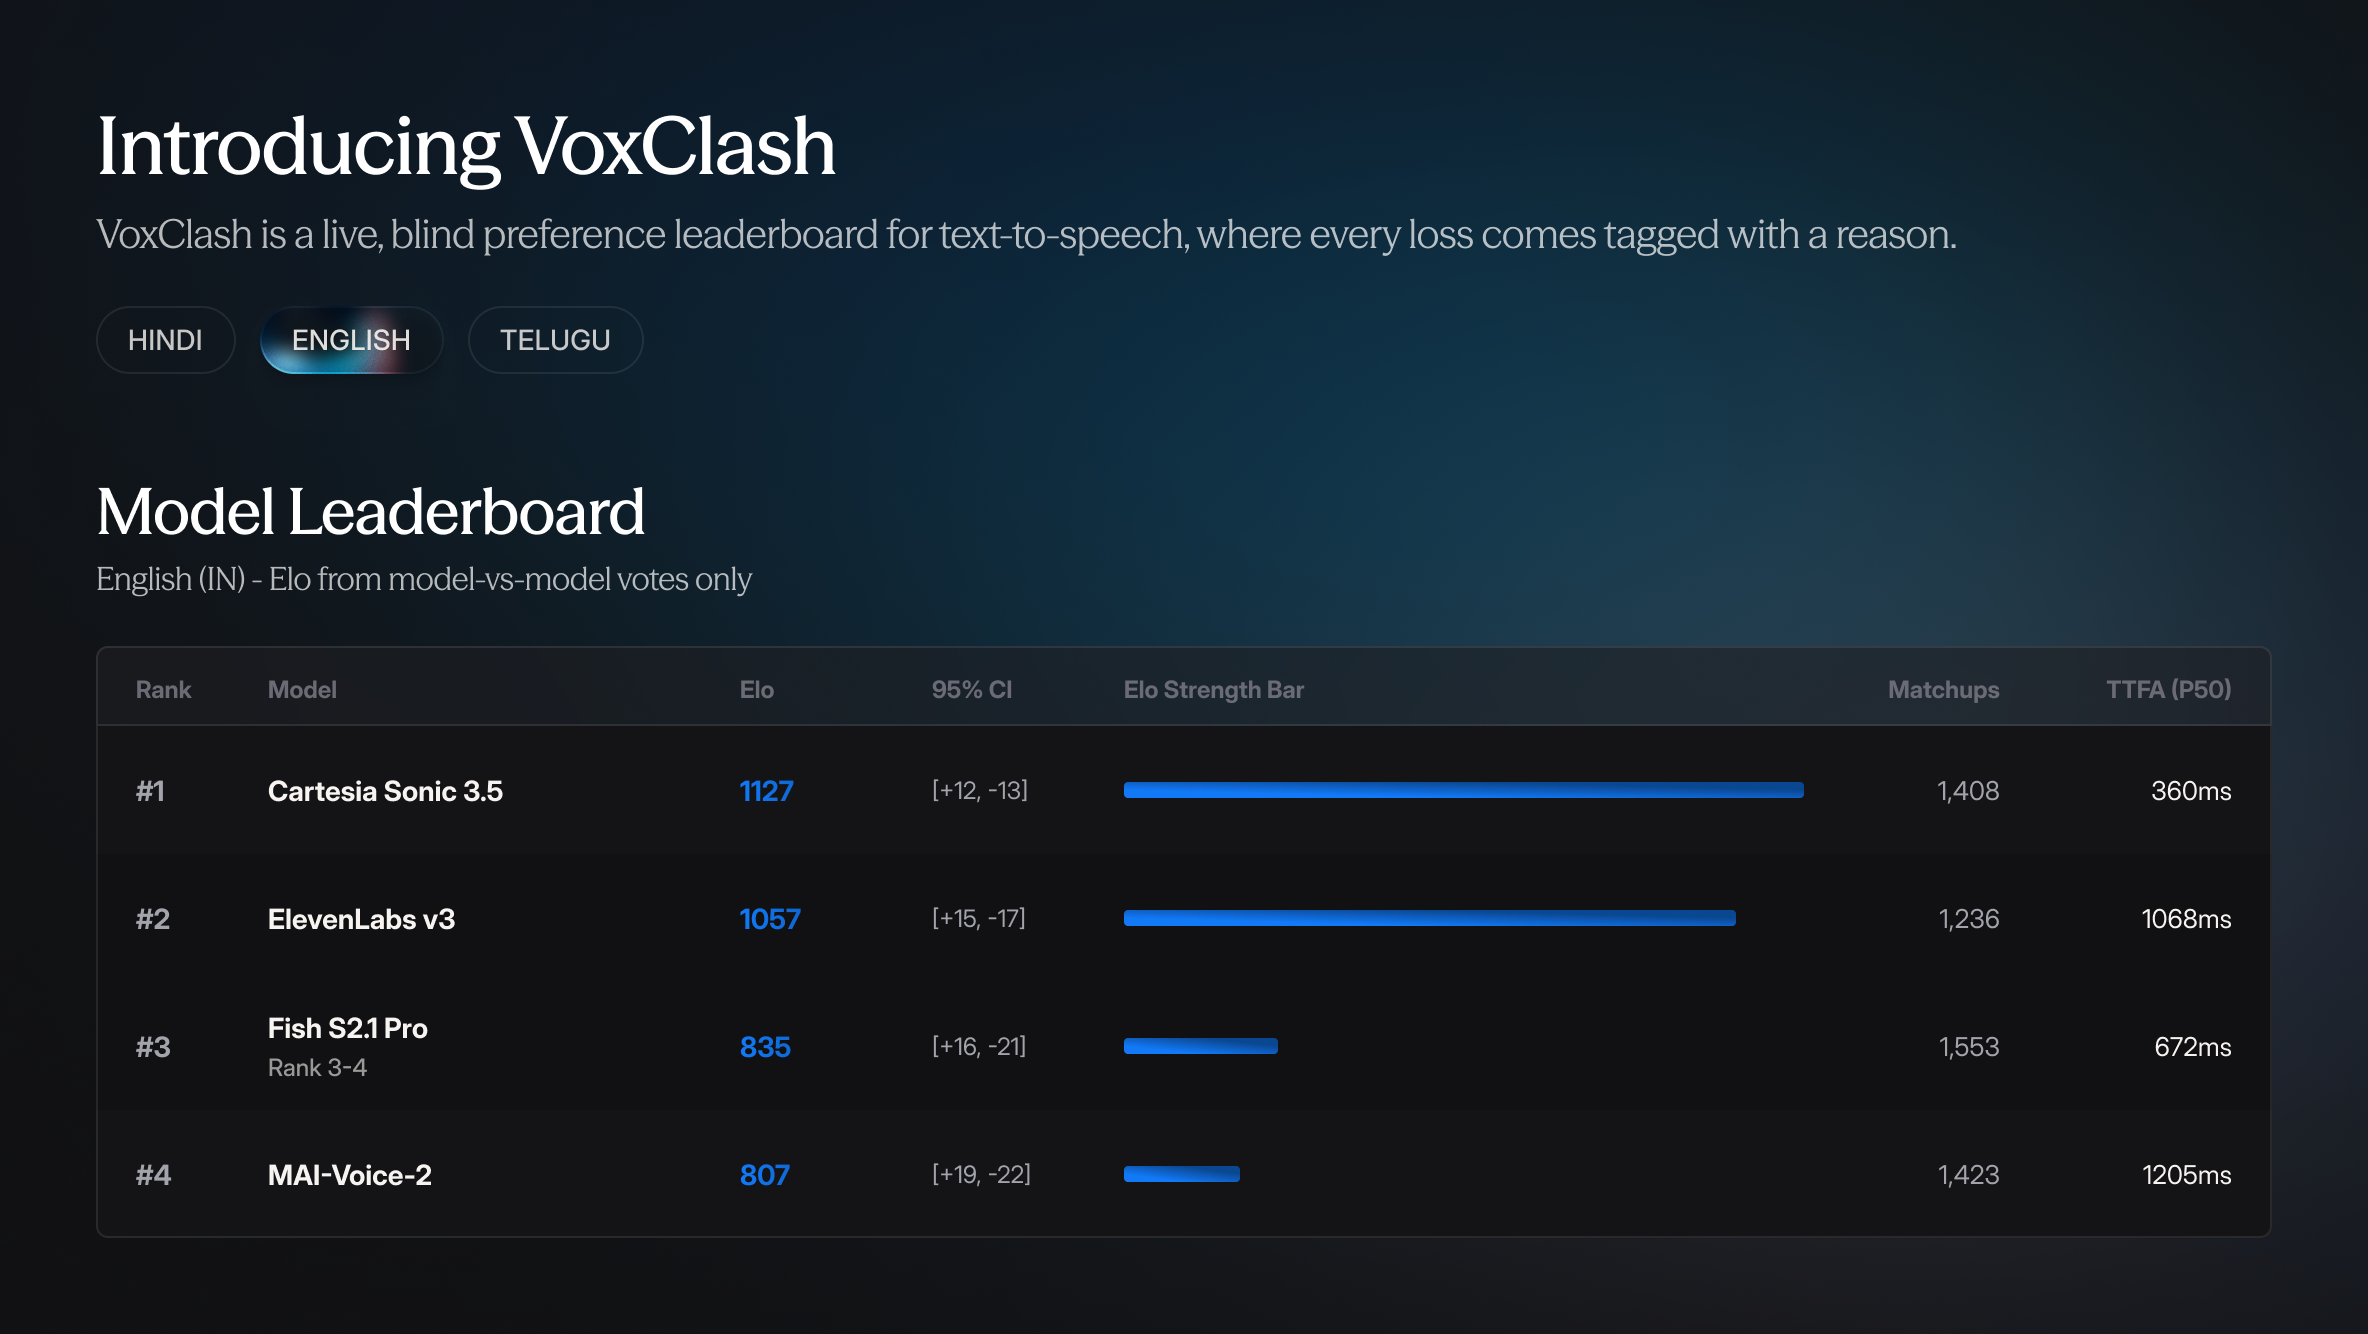
English (India) shows why every board also publishes head-to-head results. ElevenLabs v4 has the highest Elo there, yet Cartesia Sonic 3.5 won 62% of their direct matchups, the reverse of what the Elo gap predicts. ElevenLabs v4 is a recent addition, so it has fewer matchups and a wider interval.
Bradley-Terry also assumes a single strength per model, an approximation the head-to-head matrix lets you check. Telugu shows it too: ElevenLabs v4 wins 35% of its matchups against Gemini 3.1 Flash TTS where the Elo gap predicts about 49%.
The newer Sonic ranks below the older one on English (India)
Cartesia Sonic 3.6 shipped two months after 3.5. On English (India), 3.5 still ranks second and 3.6 fifth, yet the two split their direct matchups almost evenly, 51% to 49%. The newer model ranks lower without losing to its predecessor. It trails because 3.5 does better against most of the rest of the field. The two models’ intervals do not overlap, so thin sampling does not explain the gap. We have not isolated what does.
Elsewhere the upgrade shows, and its size depends on the language. Sonic 3.6 beats 3.5 in 84% of Tamil matchups and 82% of Bengali ones, but only 57% of Telugu ones. ElevenLabs v4 beats v3 in 82% of English (India) matchups but only 48% of Telugu ones, a coin flip.
A glimpse of issue tags: Open-weight models have a ton of catching up to do
Listeners can flag issues on either clip in a matchup. Here is Hindi by use case, with three proprietary models first and three open-weight models after. Each bar is the share of that model’s matchups in the use case tagged with the issue.
Gemini 3.1 Flash TTS comes closest to the line, peaking in Appointment at 9.6% for mispronunciation and 9.0% for code-switch errors. Cartesia Sonic 3.6 and ElevenLabs v4 stay under 9% on every tag.
Kokoro 82M is flagged for unnatural prosody in 64% to 74% of matchups in every use case. Indic Parler-TTS peaks at 70% for mispronunciation in Appointment, and Indic-Speak at 59% for code-switch errors in the same use case. Appointment is where four of these six models hit their highest flag rate.
The VoxClash leaderboard shows the same breakdown for the other models and languages.
Open-weight models land in the lower half on all nine boards, and the best of them sits 303 to 729 Elo points behind the leader. Those gaps imply the leader would win about 85% to 98% of decided head-to-head votes. Two open-weight models, Indic Parler-TTS and Kokoro 82M, sit in the bottom quartile of every large board they enter, along with the proprietary Fish S2.1 Pro and MiniMax HD. A buyer can rule all four out without waiting for tighter intervals at the top. These results describe one script set and one kind of listen, not research value.
Every score comes from the same blind vote
The vote is the same blind pairwise vote the first post describes, with two changes. Each model is now heard on several official catalog voices, typically one female and one male, sampled independently on each side of a trial. And pairing favors close opponents, with a fifth of draws ignoring Elo to keep exploring.
Every number above comes from one ballot, which asks one question after a full listen: which sounds more natural? Listeners pick A or B, or mark both or neither as natural, and both clips must play to the end. Issue tags ride with the vote and never move it.
We generate each clip from the provider’s official API or published weights, accept no vendor-supplied audio, and play clips as returned, with no loudness normalization.
Deccan AI operates VoxClash and also builds speech products. No vendor paid for inclusion, a voice slot or a rank.
What a rank does not measure
A rank says listeners prefer one model over another on this rater pool and these scripts. It does not cover cloning, speaker similarity, long-form consistency, streaming artifacts or cost.
Try VoxClash TTS 2.0
Pick a language and a use case, then compare the models at deccan.ai/voxclash-tts-leaderboard. The first post covers the method and the six issue tags.